Hi, I'm Mahdi
@soda4fries
Welcome to my blog
Welcome. I put things I find interesting here, if I need them later I can find them here. I think having a website is cool because everywhere else you cannot fully control how you present your information. Here you can arrange it however you want.
Latest Blog Posts
Popular Tags
A guide to deploying and managing PostgreSQL clusters on Kubernetes using the Cloud Native PostgreSQL operator
A classic Snake game I built for my company 404 page, then got addicted and added pathfinding algorithms.
A showcase of all available markdown formatting features, MDX components, and interactive elements for this blog system.
Papers
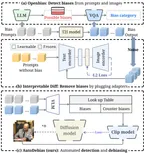
AutoDebias: Automated Framework for Debiasing Text-to-Image Models
AI image generators often pick up unwanted biases from training data — like always showing doctors as male. AutoDebias automatically hunts down these biases using vision-language models, then neutralizes them with CLIP-guided training, achieving 91.6% detection accuracy across 17 attack scenarios without breaking image quality.
arXiv:2508.00445
Low-Confidence Gold: Refining Low-Confidence Samples for Efficient Instruction Tuning
Fine-tuning large language models requires massive datasets, but most of the data is redundant. Cluster training samples, score by confidence, and pick a curated 6K subset that outperforms models trained on the full dataset — saving huge compute costs.
arXiv:2502.18978
AgileIR: Memory-Efficient Group Shifted Windows Attention for Lightweight Image Restoration
Transformer models that restore blurry or degraded images eat enormous GPU memory. AgileIR redesigns the attention mechanism to work in groups across attention heads, cutting memory use by over 50% while keeping the same image quality (32.20 dB on Set5).
arXiv:2409.06206
CFPFormer: Feature-pyramid like Transformer Decoder for Segmentation and Detection
Medical image segmentation needs models that see both fine-grained local details and big-picture context. CFPFormer combines feature pyramids with a Gaussian Attention mechanism in a transformer decoder, reaching 92.02% Dice Score on medical benchmarks — beating heavier ViT-based models.
arXiv:2404.15451